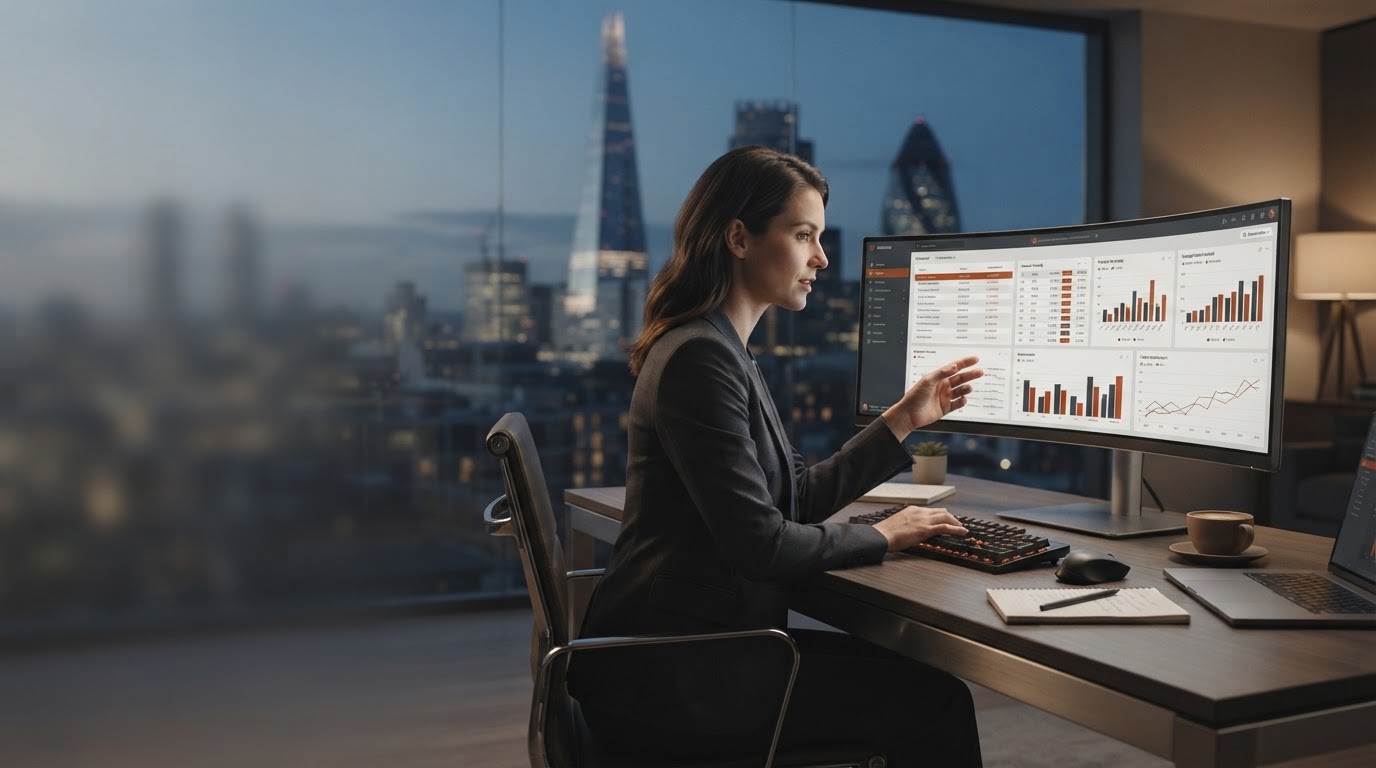
Silver Yielode data analysis dashboard used by a remote investor

Quantitative intelligence that adapts to your risk tolerance, wherever you are working from

Silver Yielode ingests market and portfolio data in real time, builds a calibrated profile of your risk appetite, and adjusts its recommendations automatically as conditions change — without requiring a desk, a trading floor, or a fixed internet connection.

Live Position Monitor Sample output
Equities — Global Risk band: Moderate +1.4%
FX — GBP/USD exposure Risk band: Conservative -0.3%
Fixed Income Risk band: Low +0.2%
Digital Assets Risk band: Elevated -2.1%
How the model reaches a recommendation

Each output is the result of a sequential process rather than a single black-box prediction. The steps below describe what happens between data ingestion and the recommendation shown in your dashboard.

Data Ingestion

Market feeds, portfolio statements, and transaction records are pulled into a unified data layer on a continuous schedule.

Normalisation

Inputs are cleaned and standardised so that figures from different brokers, currencies, and asset classes can be compared directly.

Profile Calibration

Your historical decisions and stated constraints are weighted against observed volatility tolerance to update your risk profile.

Recommendation Output

The system generates a ranked set of actions, each annotated with the confidence level and the data points used to reach it.

What "risk tolerance" means to the model

Risk tolerance is not a single number fixed at onboarding. The model treats it as a range that shifts with your trading history, your stated time horizon, and your response to previous recommendations. A remote investor managing capital between time zones will see thresholds adjust if their activity patterns or stated constraints change, rather than relying on a static questionnaire answered once.

System response pathway
Incoming data point flagged against current thresholds
Deviation measured against your calibrated risk band
Adjustment proposed with supporting rationale
Action logged and profile updated for future cycles

Two functional pillars behind every recommendation

The platform is built around predictive modelling and continuous data ingestion. Each exists to reduce the volume of manual review a location-independent investor would otherwise need to perform.

Predictive Models

Forecasts are generated from historical price behaviour, volatility clustering, and portfolio-level correlations, then cross-checked against your current risk band before surfacing as a recommendation.

  • Input windowRolling historical + live feed
  • Re-calibrationContinuous, event-triggered
  • Output formatRanked action with confidence note

Model accuracy figures are specific to each portfolio and are displayed within your dashboard after the initial calibration period, rather than quoted as a general figure here.

Real-Time Data Ingestion

Market data, account statements, and relevant macroeconomic releases are pulled continuously, so the risk profile is never based on information that is more than one cycle old.

  • SourcesMarket feeds, broker exports, macro releases
  • ProcessingStreaming, not batch
  • Latency targetSub-minute under normal load

Latency can vary with upstream feed availability; the platform surfaces a timestamp against every data point used in a recommendation.

Silver Yielode risk management module shown on a laptop used by a remote professional

Protecting capital and time when you are not at a desk

Remote professionals rarely have the luxury of monitoring positions throughout the trading day. The risk management module is built around that constraint: it watches thresholds continuously and only requires your attention when a decision genuinely needs one.

Rather than issuing constant alerts, the system batches lower-priority signals and escalates only the changes that fall outside your calibrated risk band. This is intended to reduce the time spent reviewing data, and to reduce the human error that comes from reacting to every market fluctuation individually.

  • Thresholds adjust automatically as your risk profile is recalibrated, rather than requiring manual resets.
  • Escalation logic separates routine volatility from genuine deviations, reducing alert volume.
  • Every recommendation carries a logged rationale, so decisions can be reviewed after the fact.
  • Designed to function across time zones, with no dependency on a fixed office connection.

Applied across different data types

The same ingestion and profiling pipeline is applied to several categories of financial data. The table below describes typical usage rather than guaranteed outcomes, since results depend on the quality and volume of the data supplied.

Data Type Typical Application Typical Output Processing Load
Listed equities portfolio Position-level risk banding and rebalancing prompts Ranked rebalancing suggestions with rationale High-volume, continuous
Multi-currency cash flow FX exposure monitoring for cross-border income Exposure summary with threshold alerts Moderate, event-driven
Private business revenue data Cash flow volatility assessment for self-employed income Reserve recommendation and variance flags Low to moderate, periodic
Digital asset holdings Volatility-adjusted exposure limits Band-adjusted position caps High-volume, continuous

Processing load reflects the frequency and volume of data the model handles per category; it does not represent a guaranteed return or outcome. Manual review time is reduced in proportion to the volume of data the model can process on your behalf, since this is the specific function it is designed to replace.

Data security, latency, and model training

These are the questions most frequently raised by technically-minded users before integration. For deeper detail, each answer links to the relevant specification page.

How is portfolio and account data secured in transit and at rest?

Data is encrypted in transit using industry-standard TLS, and encrypted at rest within the storage layer. Access to raw account data is restricted to the processes that require it for model calibration; it is not used to train models for other accounts.

Review security specifications →
What latency should I expect between a market event and a system response?

Under normal operating conditions, the ingestion pipeline processes new data within sub-minute windows. Latency can increase during periods of high upstream feed volume or scheduled maintenance; any delay is reflected in the timestamp attached to each data point.

Review latency specifications →
How is the predictive model trained, and does it use my data to improve itself?

Models are trained on aggregated historical market data and are recalibrated per account using that account's own activity and constraints. Individual account data is not pooled across users to retrain the shared model.

Review model training documentation →
Can I export the data and recommendations the system generates?

Recommendations, rationale logs, and the underlying data points used in each decision can be exported from your dashboard in standard tabular formats, so you retain a record independent of the platform.

Ask about export formats →
What happens if a data feed goes offline?

If an upstream feed becomes unavailable, the module flags the affected data category as stale rather than silently substituting outdated figures, and recommendations dependent on that feed are paused until the connection is restored.

See full technical FAQ →

Review your data pipeline before you commit to anything

Integration begins with a review of the data sources you intend to connect — brokerage exports, FX accounts, or business revenue records. There is no requirement to migrate your existing accounts before the first calibration cycle.

Account data is encrypted in transit and at rest, and is never pooled across users for model training.